Mixed methods research is all the rage right now in graduate school. Newly-hired professors and doctoral students are increasingly being pressured to do mixed methods research studies. But what exactly are mixed methods research studies? And why are they trending? I will answer both these questions in this blog post.
Although mixed methods research has been around a long time, much of academia agrees that it is the venerable John W. Creswell who has put forth the best guidance as to how to correctly conduct mixed methods studies. Although Creswell has published several rather involved books on the subject over the years, this blog post will focus on what he says in his shorter book, “A Concise Introduction to Mixed Methods Research” published in 2021.
Mixed Methods Research: What is it Exactly?
Prior to encountering the Creswell literature, my understanding of mixed methods studies were simply studies that had a qualitative component and a quantitative component. For example, Dörnyei and Ushioda recommended mixed methods studies when doing research on what motivates students learning a foreign language. Specifically, they recommended gathering quantitative data through surveys and psychometric instruments, and also gathering qualitative data by interviewing students about what motivates them as they are engaging in second language learning.
However, Creswell has a more nuanced approach. He says that the point of doing mixed methods research is to at some point combine the findings from the qualitative and quantitative studies and engage in meta-inference – which means coming up with overall take-home messages from the combination of these two research modalities that would not be possible to derive from either one alone.
If this is hard for you to visualize from this simple explanation, you are not alone. I also didn’t really understand what Creswell meant by this from his basic description. However, what helped me understand was when he described the three core study design used in mixed methods research, which I will repeat here.
Three Core Mixed Methods Study Designs
Creswell emphasizes in his book that there are not only three mixed methods study designs, and encourages the reader to get creative and push the boundaries of mixed methods designs so they adequately fit the research questions posed by the researcher. But if you are a doctoral student, or are otherwise new to mixed methods study designs, it’s best to start with one of these three core designs, which I will summarize here.
Convergent Design
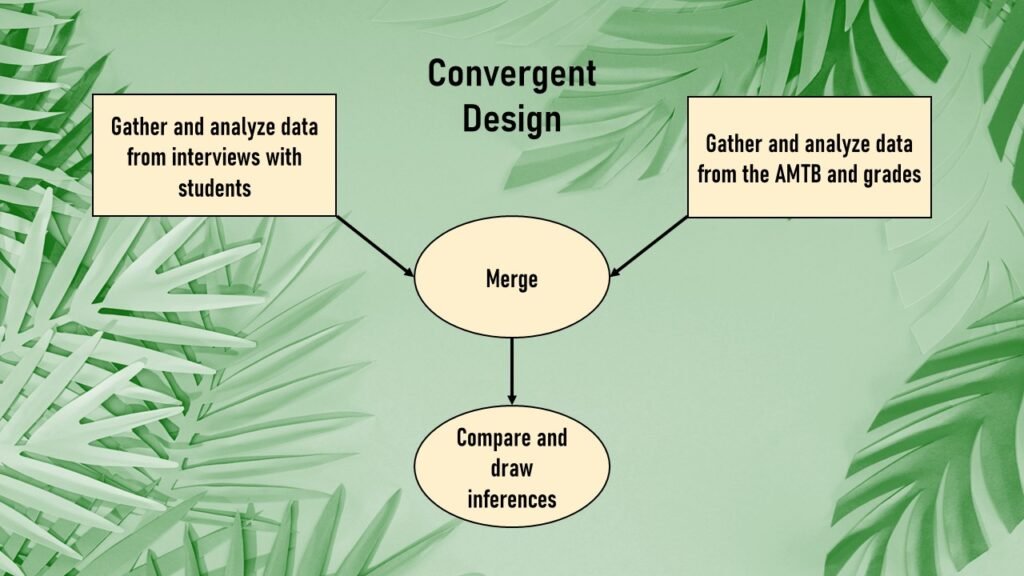
In the convergent design, the qualitative and quantitative data are gathered separately, but are meant to “converge” into an overall understanding. To carry on with the Dörnyei and Ushioda example, imagine you were a high school French teacher to students who grew up the United States (US) speaking English. To understand how their motivation to learn French related to how well they were doing in your class:
- You might gather quantitative data through noting their grades on assignments and exams, and by asking them to fill out instruments to measure motivation to learn a second language, like the Attitude/Motivation Test Battery (AMTB).
- You might gather qualitative data through interviewing students about how motivated they were, what strategies they used to learn French, and how they thought that related to their performance in your class.
Creswell recommends making diagrams to explain your study design. Here is an example of a convergent design diagram that reflects the hypothetical mixed methods study described above.
Explanatory Sequential Design
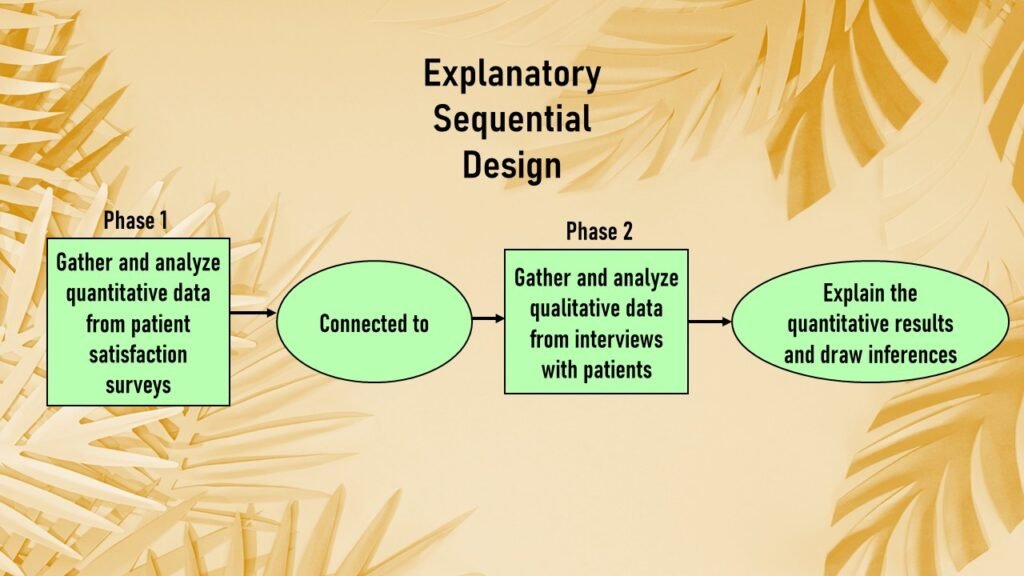
In the explanatory sequential design, first you gather quantitative data, and on the basis of what you find from the quantitative data, you gather qualitative data. As an example, imagine you were the director of a clinic.
- First, you start by administering a routine patient satisfaction survey (like the one Press Ganey uses) as your quantitative data. The Press Ganey survey covers the following domains: the care provider, the nurse or assistant, personal issues, overall assessment, access, and moving through the visit. After analyzing the results, you see that there are low scores on “personal issues” and “access”.
- Next, you would conduct interviews with patients to gather qualitative data. Your interviews could focus on why the ratings for “personal issues” and “access” were so low.
Here is a figure that reflects this hypothetical explanatory sequential design mixed methods study.
Exploratory Sequential Design
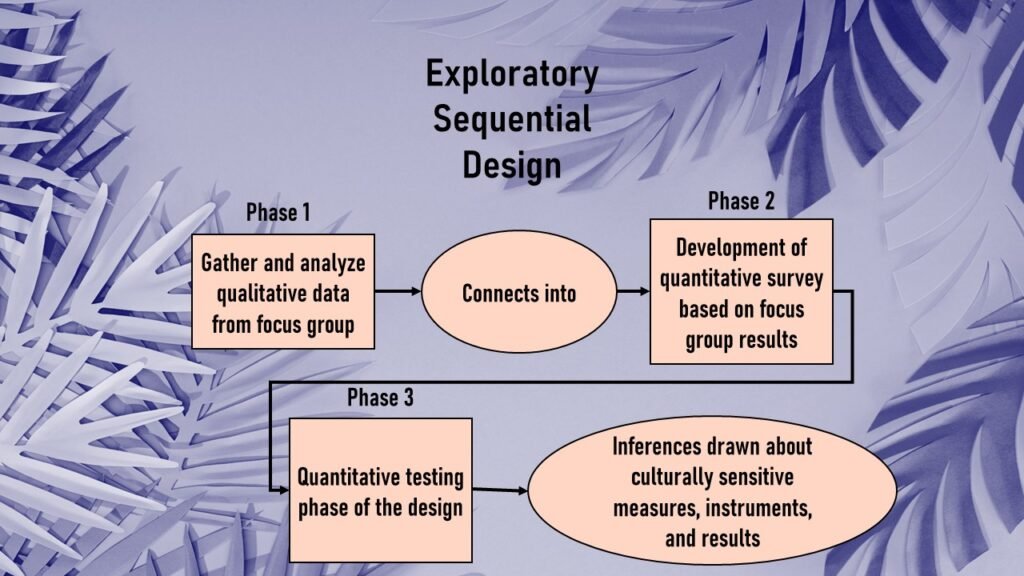
Finally, we have the exploratory sequential design. In this design, qualitative data are gathered first and analyzed, and the results inform the collection and analysis of the quantitative data. Imagine you work in the marketing department at a business which is carrying a new product. The product is a new invention, so it is hard to gauge what customers will think about it.
- First, you can hold a focus group of potential customers to gather and analyze qualitative data about the product.
- Once you analyze the themes of what the focus group discusses, based on that, you can develop a survey about the product and send it out to your customer base for feedback to collect and analyze quantitative data.
Here is a figure that reflects this hypothetical exploratory sequential design mixed methods study.
Why is Mixed Methods Research Trending?
If you are a true scientist, then you realize that study designs should not “trend”. Study designs exist to answer research questions, and depending upon your research question, you choose the proper study design. If you have a research question best answered by a qualitative approach, you should use that kind of study design. If you have a research question best answered through a quantitative approach, you should use that kind of study design.
As my description above shows, mixed methods research really only applies to very specific circumstances. So why are doctoral students being encouraged to shoehorn whatever research interests they have into a set of questions that can only be answered through mixed methods? And why are academics being advised to choose these mixed methods designs? After all, they are a lot of work, and have multiple phases. Such data-intensive study designs run the risk of never getting done – meaning that doctoral students are risking not graduating, and academics might get delayed in achieving tenure if they choose such a study design. So why is this type of design being promoted? After all, there is nothing new about it.
Here is my personal opinion: The reason why mixed methods designs are being promoted in academia is because of the pressure to publish. If you do a long, involved study that includes both qualitative and quantitative data collection, you might be able to squeeze multiple peer-reviewed publications out of one project. Academic leaders do not care about the value or appropriateness of the science produced. They aren’t interested in committing resources to sound research, or supporting students and professors who are engaging in research. All they care about is causing peer-reviewed publications to exist, and they erroneously believe that forcing everyone to do mixed methods studies will achieve this.
Of course, unless you really know what you are doing, embarking on a long mixed method study may backfire. If you don’t have much of a research background, you may end up with a bunch of data that mean nothing because you messed up the study design. You might have trouble analyzing one or both types of data you gather because you are unfamiliar with how. I think it’s really a bad idea for a college to try to force graduate students to do a mixed method study when – because they are students – they don’t have any experience. The likelihood of their success is low.
Read all of our data science blog posts!
Mixed Methods Research: The Hot New Trend in Graduate School
Mixed methods research is trending now, with doctoral students and academics being pressured to do [...]
Oct
AI or Statistics – Which Modeling Approach Should You Use?
AI or statistics – two different, interrelated approaches you can use in your scientific publication. [...]
Sep
Confidence Intervals are for Estimating a Range for the True Population-level Measure
Confidence intervals (CIs) help you get a solid estimate for the true population measure. Read [...]
1 Comment
Jun
Continuous Variable? You Can Categorize it!
Continuous variable categorized can open up a world of possibilities for analysis. Read about it [...]
2 Comments
Jun
Delete if the Row Meets Criteria? Do it in SAS!
Delete if rows meet a certain criteria is a common approach to paring down a [...]
May
Chi-square Test: Insight from Using Microsoft Excel
Chi-square test is hard to grasp – but doing it in Microsoft Excel can give [...]
May
Identify Elements of Research in Scientific Literature
Identify elements in research reports, and you’ll be able to understand them much more easily. [...]
May
Design the Most Useful Time Periods for Your Conversions
Time periods are important when creating a time series visualization that actually speaks to you! [...]
Apr
Apply Weights? It’s Easy in R with the Survey Package!
Apply weights to get weighted proportions and counts! Read my blog post to learn how [...]
Nov
Make Categorical Variable Out of Continuous Variable
Make categorical variables by cutting up continuous ones. But where to put the boundaries? Get [...]
Nov
Remove Rows in R with the Subset Command
Remove rows by criteria is a common ETL operation – and my blog post shows [...]
Oct
CDC Wonder for Studying Vaccine Adverse Events: The Shameful State of US Open Government Data
CDC Wonder is an online query portal that serves as a gateway to many government [...]
Jun
AI Careers: Riding the Bubble
AI careers are not easy to navigate. Read my blog post for foolproof advice for [...]
Jun
Descriptive Analysis of Black Friday Death Count Database: Creative Classification
Descriptive analysis of Black Friday Death Count Database provides an example of how creative classification [...]
Nov
Classification Crosswalks: Strategies in Data Transformation
Classification crosswalks are easy to make, and can help you reduce cardinality in categorical variables, [...]
Nov
FAERS Data: Getting Creative with an Adverse Event Surveillance Dashboard
FAERS data are like any post-market surveillance pharmacy data – notoriously messy. But if you [...]
4 Comments
Nov
Dataset Source Documentation: Necessary for Data Science Projects with Multiple Data Sources
Dataset source documentation is good to keep when you are doing an analysis with data [...]
Nov
Joins in Base R: Alternative to SQL-like dplyr
Joins in base R must be executed properly or you will lose data. Read my [...]
Nov
NHANES Data: Pitfalls, Pranks, Possibilities, and Practical Advice
NHANES data piqued your interest? It’s not all sunshine and roses. Read my blog post [...]
Nov
Color in Visualizations: Using it to its Full Communicative Advantage
Color in visualizations of data curation and other data science documentation can be used to [...]
Oct
Defaults in PowerPoint: Setting Them Up for Data Visualizations
Defaults in PowerPoint are set up for slides – not data visualizations. Read my blog [...]
Oct
Text and Arrows in Dataviz Can Greatly Improve Understanding
Text and arrows in dataviz, if used wisely, can help your audience understand something very [...]
Oct
Shapes and Images in Dataviz: Making Choices for Optimal Communication
Shapes and images in dataviz, if chosen wisely, can greatly enhance the communicative value of [...]
Oct
Table Editing in R is Easy! Here Are a Few Tricks…
Table editing in R is easier than in SAS, because you can refer to columns, [...]
Aug
R for Logistic Regression: Example from Epidemiology and Biostatistics
R for logistic regression in health data analytics is a reasonable choice, if you know [...]
272 Comments
Aug
Connecting SAS to Other Applications: Different Strategies
Connecting SAS to other applications is often necessary, and there are many ways to do [...]
Jul
Portfolio Project Examples for Independent Data Science Projects
Portfolio project examples are sometimes needed for newbies in data science who are looking to [...]
Jul
Project Management Terminology for Public Health Data Scientists
Project management terminology is often used around epidemiologists, biostatisticians, and health data scientists, and it’s [...]
Jun
Rapid Application Development Public Health Style
“Rapid application development” (RAD) refers to an approach to designing and developing computer applications. In [...]
Jun
Understanding Legacy Data in a Relational World
Understanding legacy data is necessary if you want to analyze datasets that are extracted from [...]
Jun
Front-end Decisions Impact Back-end Data (and Your Data Science Experience!)
Front-end decisions are made when applications are designed. They are even made when you design [...]
Jun
Reducing Query Cost (and Making Better Use of Your Time)
Reducing query cost is especially important in SAS – but do you know how to [...]
Jun
Curated Datasets: Great for Data Science Portfolio Projects!
Curated datasets are useful to know about if you want to do a data science [...]
May
Statistics Trivia for Data Scientists
Statistics trivia for data scientists will refresh your memory from the courses you’ve taken – [...]
Apr
Management Tips for Data Scientists
Management tips for data scientists can be used by anyone – at work and in [...]
Mar
REDCap Mess: How it Got There, and How to Clean it Up
REDCap mess happens often in research shops, and it’s an analysis showstopper! Read my blog [...]
Mar
GitHub Beginners in Data Science: Here’s an Easy Way to Start!
GitHub beginners – even in data science – often feel intimidated when starting their GitHub [...]
Feb
ETL Pipeline Documentation: Here are my Tips and Tricks!
ETL pipeline documentation is great for team communication as well as data stewardship! Read my [...]
Feb
Benchmarking Runtime is Different in SAS Compared to Other Programs
Benchmarking runtime is different in SAS compared to other programs, where you have to request [...]
Dec
End-to-End AI Pipelines: Can Academics Be Taught How to Do Them?
End-to-end AI pipelines are being created routinely in industry, and one complaint is that academics [...]
Nov
Referring to Columns in R by Name Rather than Number has Pros and Cons
Referring to columns in R can be done using both number and field name syntax. [...]
Oct
The Paste Command in R is Great for Labels on Plots and Reports
The paste command in R is used to concatenate strings. You can leverage the paste [...]
Oct
Coloring Plots in R using Hexadecimal Codes Makes Them Fabulous!
Recoloring plots in R? Want to learn how to use an image to inspire R [...]
5 Comments
Oct
Adding Error Bars to ggplot2 Plots Can be Made Easy Through Dataframe Structure
Adding error bars to ggplot2 in R plots is easiest if you include the width [...]
Oct
AI on the Edge: What it is, and Data Storage Challenges it Poses
“AI on the edge” was a new term for me that I learned from Marc [...]
Jun
Pie Chart ggplot Style is Surprisingly Hard! Here’s How I Did it
Pie chart ggplot style is surprisingly hard to make, mainly because ggplot2 did not give [...]
5 Comments
Apr
Time Series Plots in R Using ggplot2 Are Ultimately Customizable
Time series plots in R are totally customizable using the ggplot2 package, and can come [...]
Apr
Data Curation Solution to Confusing Options in R Package UpSetR
Data curation solution that I posted recently with my blog post showing how to do [...]
Apr
Making Upset Plots with R Package UpSetR Helps Visualize Patterns of Attributes
Making upset plots with R package UpSetR is an easy way to visualize patterns of [...]
11 Comments
Apr
Making Box Plots Different Ways is Easy in R!
Making box plots in R affords you many different approaches and features. My blog post [...]
Mar
Convert CSV to RDS When Using R for Easier Data Handling
Convert CSV to RDS is what you want to do if you are working with [...]
Mar
GPower Case Example Shows How to Calculate and Document Sample Size
GPower case example shows a use-case where we needed to select an outcome measure for [...]
Feb
Querying the GHDx Database: Demonstration and Review of Application
Querying the GHDx database is challenging because of its difficult user interface, but mastering it [...]
Feb
Variable Names in SAS and R Have Different Restrictions and Rules
Variable names in SAS and R are subject to different “rules and regulations”, and these [...]
Feb
Referring to Variables in Processing Data is Different in SAS Compared to R
Referring to variables in processing is different conceptually when thinking about SAS compared to R. [...]
Jan
Counting Rows in SAS and R Use Totally Different Strategies
Counting rows in SAS and R is approached differently, because the two programs process data [...]
Jan
Native Formats in SAS and R for Data Are Different: Here’s How!
Native formats in SAS and R of data objects have different qualities – and there [...]
Jan
SAS-R Integration Example: Transform in R, Analyze in SAS!
Looking for a SAS-R integration example that uses the best of both worlds? I show [...]
Dec
Dumbbell Plot for Comparison of Rated Items: Which is Rated More Highly – Harvard or the U of MN?
Want to compare multiple rankings on two competing items – like hotels, restaurants, or colleges? [...]
2 Comments
Sep
Data for Meta-analysis Need to be Prepared a Certain Way – Here’s How
Getting data for meta-analysis together can be challenging, so I walk you through the simple [...]
Jul
Sort Order, Formats, and Operators: A Tour of The SAS Documentation Page
Get to know three of my favorite SAS documentation pages: the one with sort order, [...]
Nov
Confused when Downloading BRFSS Data? Here is a Guide
I use the datasets from the Behavioral Risk Factor Surveillance Survey (BRFSS) to demonstrate in [...]
2 Comments
Oct
Doing Surveys? Try my R Likert Plot Data Hack!
I love the Likert package in R, and use it often to visualize data. The [...]
3 Comments
Oct
I Used the R Package EpiCurve to Make an Epidemiologic Curve. Here’s How It Turned Out.
With all this talk about “flattening the curve” of the coronavirus, I thought I would [...]
Mar
Which Independent Variables Belong in a Regression Equation? We Don’t All Agree, But Here’s What I Do.
During my failed attempt to get a PhD from the University of South Florida, my [...]
Aug
Mixed methods research is trending now, with doctoral students and academics being pressured to do it. But is it always the right approach? Read my blog and find out!
